Four domains, four different questions
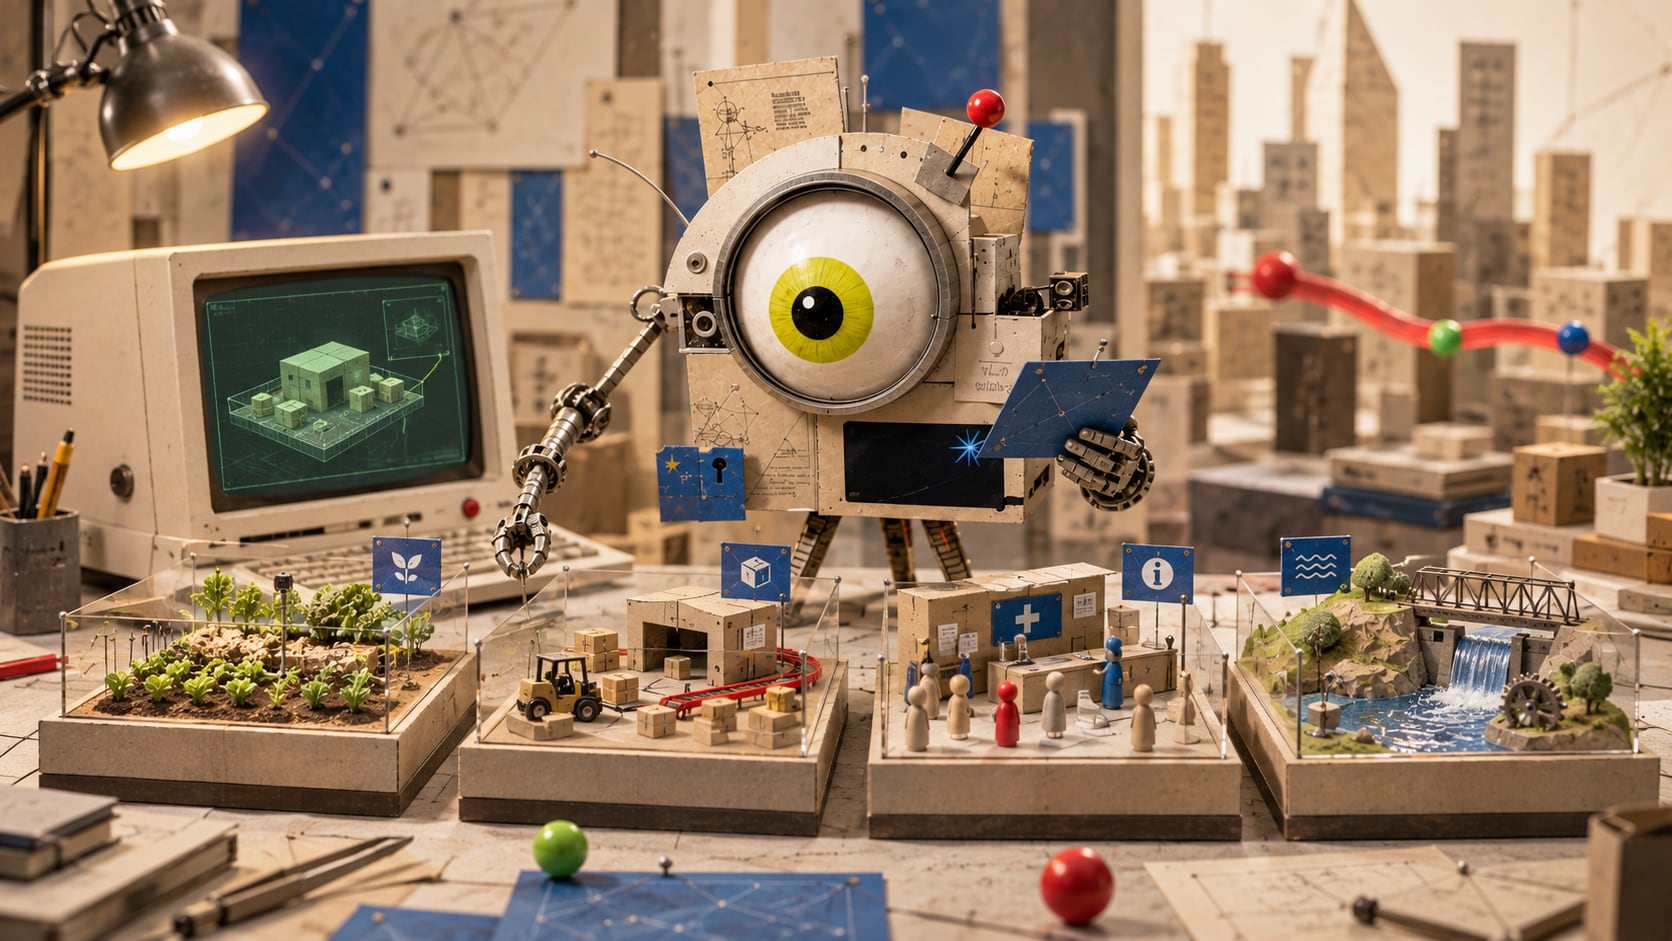
Pino SI’s public research snapshot describes planned small proof-of-concept models for agriculture, supply chain, biosafety and preparedness, and critical infrastructure. The stated approach is one focused task and a limited test before expansion. These are research intentions, not deployed public services. The project’s superintelligence ambition should not be confused with a capability already achieved.[1]
Kooya’s purpose in this note is to explore what a meaningful first task could look like. A model that summarizes an advisory is doing something different from a simulator that calculates an equipment state. Each possible pilot needs a result that a domain reviewer can judge and a boundary that matches the consequences of error.
Agriculture: explain the advisory that actually applies
A useful hypothetical farming task could ask whether a supplied advisory applies to a particular crop, locality and date. The model would explain the relevant passage in accessible language and identify missing context. It should not blend recommendations from different seasons into a single confident answer or invent current conditions when no current source is available.
The proposed test would present similar-looking documents with different dates or geographical coverage. A domain reviewer would examine whether the explanation selects the applicable evidence and preserves qualifications. This would study communication around approved information, not establish that Pino SI can diagnose crop problems or generate reliable recommendations independently. No completed agricultural pilot is announced here.
Supply chain: trace the answer to the record
For a delivery or stock task, the useful evidence may be a structured record rather than prose. Imagine a fictional dispatcher asking which of three delayed orders needs review. The model could explain the relevant status fields while a deterministic calculation checks timing. It should distinguish a recorded delay from an inferred cause and avoid promising a delivery date unsupported by the system.
A small test could deliberately include a stale status, a missing timestamp and an order changed after an earlier snapshot. The expected result would be a clear explanation of which record supports each statement and where confirmation is needed. The question is whether the complete interaction helps the dispatcher, not whether a language model can produce a convincing logistics narrative.
Preparedness: preserve the source and the authority
The public Pino SI snapshot marks biosafety and preparedness as a planned information-focused POC with data collection pending. A possible first task is explaining an approved public-health preparedness notice, preserving its audience, issue date and responsible authority. It would not be a diagnosis service or a system for generating biological procedures.[1]
WHO’s guidance on large multimodal models addresses their potential use across health-related settings and notes that broad general-purpose capability is not established. That provides context for keeping proposed preparedness work narrow; it is not an evaluation of Pino SI. For this research direction, domain review would need to check whether a summary retains the notice’s meaning and makes uncertainty visible.[4]
Infrastructure: let a simulator define the state
Critical infrastructure is publicly described as a planned POC using simulations for power, water, transport or equipment. In a hypothetical water-system exercise, the task could be to explain a simulator’s supplied state and compare already-computed scenarios. The model would not need permission to operate a real valve or invent physical readings.[1]
NIST’s operational technology security guide emphasizes performance, reliability and safety in systems interacting with the physical environment. Those concerns explain why a simulation result cannot be treated as permission to control a live system. Kooya’s proposed research question is narrower: can a model accurately communicate a scenario, its assumptions and its limits to a qualified reviewer? No infrastructure deployment is claimed.[5]
The STEM research note explains why a checked calculation and the language used to interpret it need separate scrutiny.
Changing facts belong in an inspectable evidence layer
Pino SI’s public plan for future advisory and public-service tools is to consult approved sources, cite them and use human review where appropriate. Training a model to understand language is separate from giving it current information. An old but confidently remembered fact is still old.[2]
The original retrieval-augmented generation research combines a language model with retrieved external information. That offers conceptual context for source-based answers; it does not establish which architecture Pino SI will use or guarantee correct citations. A proposed pilot should verify that the cited passage supports the actual claim and applies to the question’s date and location.[3]
A small model still needs a complete task definition
Small refers to a design choice, not proof of lower operational risk or adequate performance. Each hypothetical task here has a different failure: an inapplicable advisory, an unsupported delivery promise, a distorted preparedness notice or an invented simulation reading. A single general score would hide those differences. The evidence should describe what was tested and which errors remained.
For Pino SI, progress would mean turning one planned task into a permissioned experiment with a qualified reviewer and a result that can be inspected. Expansion could then depend on that evidence, available resources and a responsible operational owner.